

Product · Benchmark
AI Quality Pipeline benchmarking
I owned the benchmarking across nine models, separating validity from correctness to show how much grounded generation with validation and error correction beats direct prompting.
Article ↗Senior Machine Learning Scientist at Salesforce
AI should amplify humanity — not diminish it.
I've spent the past several years making generative AI and agents more reliable: evaluation systems, benchmarks, validation pipelines, and recovery mechanisms that test whether AI actually works.
Now I work on AI that adapts to the person in front of it — how they communicate, collaborate, decide, delegate, and exercise control. Human diversity is not noise to be averaged away.
NowLeading User-Specific Interaction Learning (USIL), an open research agenda · Senior ML Scientist at Salesforce
Selected highlights
Humanity in AI
Building AI that expands human agency, creativity, and possibility.
The research agenda I lead
User-Specific Interaction Learning (USIL)
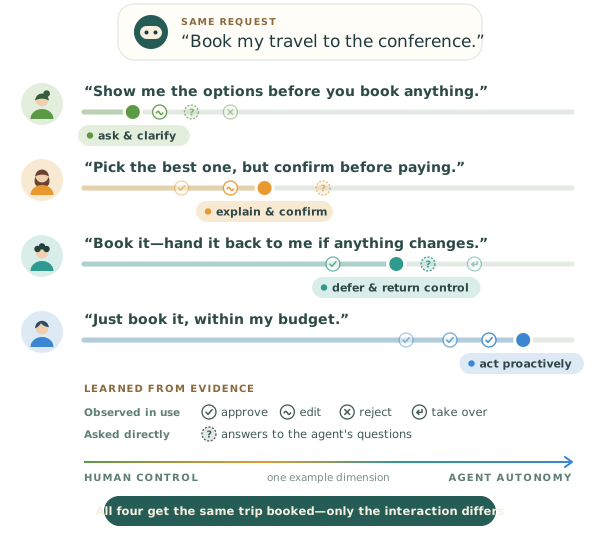
I lead USIL, an open research agenda and community on how AI agents can learn when to ask, act, explain, or hand back control for each person — from that person's own approvals, edits, takeovers, and answers.
The question behind my work
Ask two people to describe a great assistant and you get two incompatible answers. One wants it to just handle things; the other wants to be consulted before anything is spent. Same agent, same action — one person delighted, the other's trust damaged.
Most preference data measures what an agent produces, and that converges across people. How the work should be done — when to ask or act, how much to verify — diverges by person, and averaging destroys it. Every override, edit, and takeover is a preference being expressed; almost nobody reads it as how this person wants the work done.
What I believe
What people actually do — correct, override, take control, redo, abandon — says more about how they want to be served than anything they would put in a settings panel.
The variance between people is the most valuable thing in the data. Averaging it produces an agent that is acceptable to everyone and right for no one.
What I would like to exist is a portable memory of how you want work done — owned by you, inspectable by you, and carried into any new agent or product so it immediately knows how to work with you.
Where this started
Counting people outside a boba shop.
The question that keeps pulling me back is a human one.
At nineteen, I stood outside a boba shop counting who actually walked in because I trusted behavior more than survey answers. Since then, I've kept returning to the same belief: people are messy, diverse, contextual — and far more interesting than an average.
For thousands of years, we've tried to better understand ourselves and one another. AI turns that ancient challenge into a technical one: can we build intelligence that understands humanity without flattening it?
The future I want to help build is one where AI expands human agency, creativity, and possibility while preserving what makes each of us distinct.
Open questions
It would be easy to assert that everyone is unique and stop there. The interesting version is falsifiable, and I don't think anyone has answered it:
The full argument
August 2026
5 min read
What the pilot found
August 2026
10 min read
Selected work
A few projects I'm proud of. The full story — every product, paper, and patent, in three acts — is on the Work page.
Product · Benchmark
I owned the benchmarking across nine models, separating validity from correctness to show how much grounded generation with validation and error correction beats direct prompting.
Article ↗
Product
Generates transformations in a low-resource language from sample input and output, then compiles, runs, and checks the result — leaving uncertain mappings blank for review instead of guessing.
Article ↗
Research · Benchmark · ICLR 2026
300 enterprise tasks from real user interviews, run in live Salesforce sandboxes. Agents that do well on general desktop benchmarks fall below 5% here.
Paper ↗
Research · Benchmark · ICSE 2026 · DL4C at NeurIPS 2025
A benchmark of 228 high-coverage Java repositories that catches agents weakening tests to fake a successful migration. The best model migrated 52.3% of projects to JDK 17.
Paper ↗Beyond the desk
The parts of the work that happen in rooms rather than repositories.

Programming Advisor, 28th Forum
I proposed and led an AI panel called Agentic AI: The Rise and Future — set the framing, wrote the questions, and recruited the speakers myself: Salesforce COO Vivienne Wei, Liquid AI founder Ramin Hasani, former Alibaba VP Tu Zipei, and Harvard professor Boaz Barak. Several hundred people came. I also coordinated a technology and business panel with leaders from BrainCo and Cheetah Mobile.

2026
A weekend among people building things from nothing, mostly to hear how they decide what is worth building. The same pull turned up much earlier: awards at the Shanghai Internet+ and Lin Gang Bei innovation and entrepreneurship competitions.
Judge and panelist, 2025
Judged the hackathon and spoke on the panel for underrepresented builders, mostly about what the early years of a research-and-engineering career actually look like from the inside.
Award winner, March 2025
Our team built Sublime Force, an agent for insurance eligibility verification — an unglamorous healthcare bottleneck that turns out to be a good fit for agents precisely because the rules are fussy and the verification is mechanical.
Path
2024 —
Agent evaluation and generative AI quality for enterprise integration, behind MuleSoft Vibes.
2023 – 2024
MuleSoft's first generative AI features, from foundational research to General Availability.
2022 – 2023
CS109a and CS109b, Data Science I and II.
Sep – Dec 2022
Bioacoustic classification of rare tropical species from field recordings, where a wrong label is a species you stop looking for.
Summer 2022
Classifying integration patterns across Mule applications: the first look at the codebase the generative work would later have to reason about.
2021 – 2023
Cross-registered at MIT for computer vision and natural language processing. Applied ML for transportation and conservation.
2020
Shanghai. Measuring what shoppers did rather than what they said they wanted.
2017 – 2021
School of Management, with an exchange year at UC Santa Barbara. Designed learning software for older adults — the project that first made the problem legible, since mainstream interfaces so plainly assumed users who looked nothing like them.

